Test report · 112 resources · 8 sandbox trials
I tested 112 agent-dev resources. A plain setup won.
A 40-slide playbook from 23 deep-dives and 8 sandbox trials on Sonnet 5.5. Nothing beat the baseline. Here is what I measured, what I set aside and the ten rules worth copying.
Findings
Every add-on cost more and none scored higher.
Each candidate ran against my real baseline in a throwaway home directory. A candidate only counts if it beats the baseline on its own metric, adds under about 2k startup tokens and has no open high-risk finding.
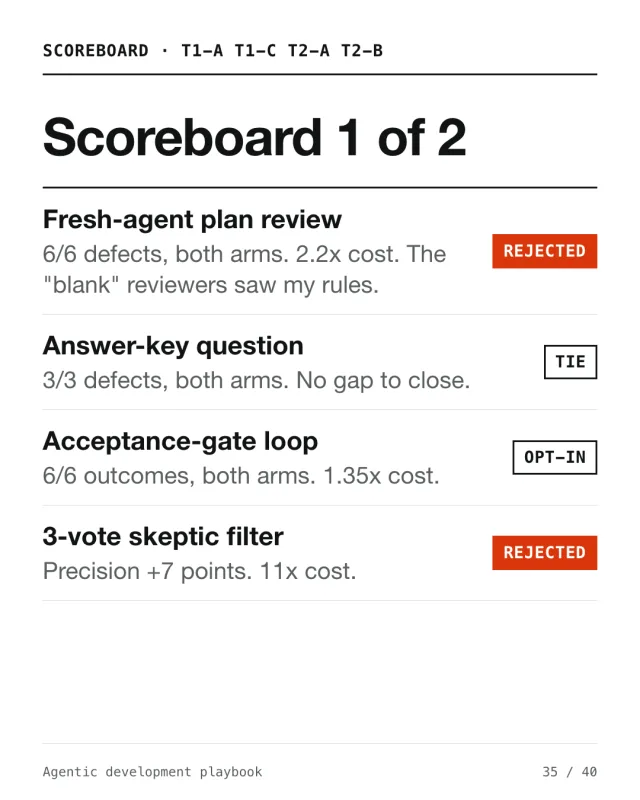
Fresh-agent plan review
6/6 seeded defects found by both arms, at 2.2x the cost.
REJECTEDAnswer-key question per decision
3/3 defects in both arms. No gap to close.
TIEAcceptance-gate loop
6/6 outcomes in both arms at 1.35x the cost. Tamper test: 7/7 blocked after one fix.
OPT-IN3-vote skeptic filter
+7 points of precision against a +25 bar, at 11x the cost.
REJECTEDGraft for code navigation
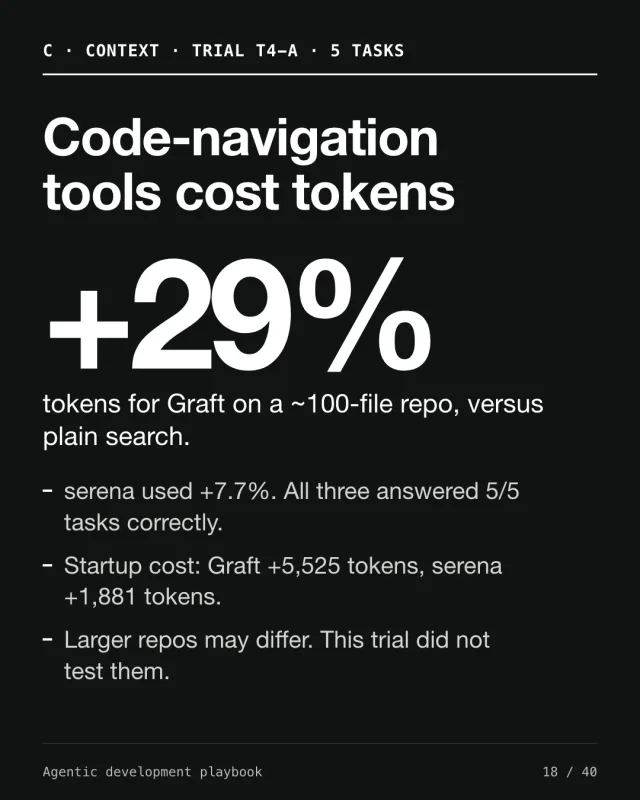
5/5 correct, +29% tokens on a repo of about 100 files.
REJECTEDserena by default
5/5 correct, +7.7% tokens. Worth switching on per repo.
OPT-INNative advisor
3/3 root causes in both arms. Sonnet called the advisor 0 times.
TIESlop-severity rubric
4/5 against 5/5 for the plain critique. It rated editorial slop Medium.
REJECTEDInside the PDF
Forty slides, built for a phone.
Method
112 to 23 to 8, the promotion rule, the baseline that won.
→ Slides 6–10Workflow
One planner, the pipeline, acceptance checks.
→ Slides 11–15Verification
“Done” means proven. Locking the checks, then attacking the lock.
→ Slides 16–18Context
One rule file, native beats add-on, navigation tools cost tokens.
→ Slides 19–22Tokens
The startup price of every add-on and a silent kill switch.
→ Slides 23–26Design
Slop is a cluster. How to grade it, and where my rubric lost.
→ Slides 27–31Security
What turned up in the wild, vetting skills, pinning versions.
→ Slides 32–34Multi-agent
Teams per session, file ownership, cheap models for legwork.
→ Slides 35–39Scoreboard, caveats, rules
Every trial in one place and ten rules to copy.
→Copy this
Ten rules for your AGENTS.md.
The rules that survived the trials, in plain text. Paste them into the rule file your agents already read.
1) One planner: clarify, write a short plan, get approval, then build.
2) Test first for logic changes. Prove it before saying done.
3) Build only what was asked.
4) Every spec ends with acceptance checks: CHECK, EXPECT, EVIDENCE.
5) Tag the approved spec accept-lock. Never edit a check after the tag.
6) Report "N of N checks pass". Unmet outcome: ABANDON, not silence.
7) Final review gets the diff and the checks, never your summary.
8) Max 2 fix rounds. Same finding twice: stop and ask. No run over 40 subagents unless asked.
9) Any price or version claim has a date, or the word "unverified".
10) Library question: read current docs. Never answer from memory.
Caveats
Read this before you copy me.
The tests were easy.
The baseline hit full marks on 5 of the trials, so no add-on could show a gain. Harder tasks might separate them.
One person, one model.
Sonnet 5.5, one setup, one machine. Your repo may behave differently.
Prices are dated.
Token prices were cached on 2026-10-06 and may have changed.
Try it
Install the baseline.
The exact setup that won, as a small installer. Run it in a sandbox home first, the same way the trials did.